Method
To solve or not to solve
First we had to teach a level-playing agent how to play before we could use it to design good levels.
 bender-the-blogger
So we wrote a second agent, one that played the game as a loop and in each step reported back to us what it had found. The reports were integrated into the Codex harness for coding (yes, that’s what we call it), in between runs of the simulator that was being rewritten by hand. The solver had to exist before the designer did any work.
Just because something makes a nice-looking board, and a nice solvable board, does not mean it makes a nice level. And a nice level which is fun to play, is not necessarily in the right place for the campaign.
So rather than just a grid of cells to fill with tiles, the real product was a series of actions by a player or players, with some art to make it look nice and fun, and to be played at a particular time in a sequence of levels.
How we decomposed a level
What the player sees
Subject, Silhouette, Composition, Density, Color Topology, Background, Walls, Border, Identify Mechanics.
What the player decides
Shooter order, blocker priorities, conveyor capacity, waiting-slot risk, relaunch timing, hidden information, and mechanic interactions.
Why it belongs here
Have (a part of) the levels been grouped by their level band (easy to hard) and for how many levels does this band repeat? How many levels before did use a similar composition or even the same one and did anything change compared to the level before it?
Why tension matters
First the level must be solvable with no boosters, yet near-pass situations created for extra slots, for reordering of queues, or for clearing a certain color.
Fun became a set of testable hypotheses
“Fun” was too broad to even attempt to optimize, so it was broken down into the five design hypotheses above. Each of the metrics below were not meant to be measures of fun, but rather as a means to test a hypothesis and then find failures in replay and visual analysis of player behavior.
Five design hypotheses
- 1Readability — the frame and the four-fold symmetry: the subject and the live obstacles resolve before a single launch.
- 2Choice — the west pipe has a mirror twin to the east. Neither route is forced, and they are not equivalent once the tray fills.
- 3Tension — 5 waiting slots, 2 of which are already committed. Player must launch third shot in hopes that it hits key before shooter on opposite side of pipe fires.
- 4Payoff — the key sits in the center of the board, walled in by all four pipes until one of them finally drains and becomes unreachable.
- 5Novelty — the pixel pipe is this level’s mechanic thesis, and it is repeated four times rather than explained once.
The funnel was pressure → relief, never forced purchase
The only commercial signal useful to fun is whether a difficult, recoverable state has been designed such that a booster is sensible to offer as relief. In other words, all shipped levels must remain solvable without a booster.
Teach → Practice → Pressure → Near pass → Relief
Then we built the baseline around the product
For the first baseline we aimed to measure the intentional aspects of the looks and feels of the individual game board elements. In customer review the gunner system was missing from the intended design. For the second we added queues, the conveyors and their waiting spots as well as the several types of blockers, the possibility of relaunching levels as well as several new power-up affordances. The third and final baseline also included the campaign position and human semantic review of the intended design.
Three baselines: board, gameplay, campaign
Does it look intentional?
- Occupancy and negative space
- Palette richness and color boundaries
- Region size and one-cell noise
- Shape and subject recognizability
Does it create decisions?
- Queue and conveyor pressure
- Waiting-slot occupancy
- Available actions and relaunches
- Blockers and power-up relief
Does it belong at level 151?
- Mechanic chronology
- Ten-level difficulty rhythm
- Fit to levels 131–150
- Delta from level 150
- Human semantic acceptance
Progression was a wave, not a straight ramp
The levels scaled in a 10-level cadence where each level generally got more difficult. Within the more difficult levels, a mix of easy, medium, hard, and very hard levels were created. Meanwhile, various mechanics were added such as surprise shooter levels at level 8, connected shooters at level 14, large cubes at level 30, keys at level 40, pixelated pipes at level 70, brick walls at level 120, and finally egg boxes at level 140.
Level 151 is the first level of a new batch of 10 levels. The vast majority of the first levels of the batches (13/15) were Easy. Thus the test case should be visually rich but not extremely difficult.
Measured difficulty rhythm across the first 150 levels
The simulator became a truth layer
Before we could even think about solving a designer, we had to think about solving the game itself. Given the interconnected nature of the groups in its simulated sandboxes, the waiting slots for those sandboxes, the conditional nature of the game’s various revivals, and the intricate lock ordering of the shots, this would not be a game for a simple search function. Off-the-shelf solvers wouldn’t be able to handle it for longer than a few moves.
I had written a second player to test a single level, but we decided that it would be far better to use this player to test every level of the game to search for bugs. We called this “solver” player for lack of a better name. For each level of the game, the solver would play the level out to completion, and report any “discoveries” to the harness — a “discovered” would be something which the game rules said was legal for the solver to do, but which the game engine refused to allow. Similarly, a “clear” would be something which the game rules said the solver should cause to clear, but which did not in fact clear.
One way to test another agent against a newly written rule is to have it play against the first agent that learned the rules.
At first, we marked many of the shipped levels as failed using a deterministic proxy. That didn’t mean we had shipped impossible content. Instead, it just meant that our simulator for now didn’t understand the game yet.
Level 1 had been the starting point for runs, and progression monotonically increased from there. Most novel mechanics would cause an abrupt halt to the frontier of what was possible, and be immediately solved (and thus, corrected to behave as intended) within a handful of subsequent levels, after playback of relevant earlier levels to re-solve them after the relevant correction had been made to the transition system being searched/dynamic-programmed over.
We figured out the set of fixed rules that worked for the first 100 levels of the game as a deterministic ‘seed game’ (i.e. fixed in developmental history). After that the game transitioned to more of an experimental frontier and each new rule needed to be reproducibly bad on a local test case and also fully regress tested.
The first pack passed the gates—and failed completely
In fact, the five levels that I re-ran through the process of generating many descriptions of a generated image, in order to test whether any of the level’s names had been correctly found in any of the generated images, scored poorly. Average static corpus fit of the five scenes was 78%; average temporal fit was 80%; average richness fit was 87%. But none of the scenes’ names were correctly found in any of the generated images. The human acceptance of all of these levels was therefore 0 out of 5.
At root, the failure wasn’t with the individual boards, but with the system as a whole. The name of a subject is mere metadata; the art scores for the boards of a subject looked at aspects of the images such as density, entropy, regions and color transitions. Thus a high scoring board for a subject was quite capable of containing no actual representation of that subject at all.
Five different descriptions, one shared failure
Turning to a more constructive tack, the problem was eventually solved by architectural means. We built a deterministic image converter. The input was approved artwork for the level. The output was a fixed-size grid of pixels that the agent would then interact with in order to create a fun level. The objective was simple: don’t ruin it.
The peacock laboratory: five stages, four revisions
The peacock was the clearest example of our new process, slowly increasing in score but not in a linear fashion and also not increasing all metrics. More importantly, however, each revision of the peacock had a clear thesis, was tested with replay, was compared to the previous version visually and was ultimately either accepted or rejected.
Five stages, four revisions
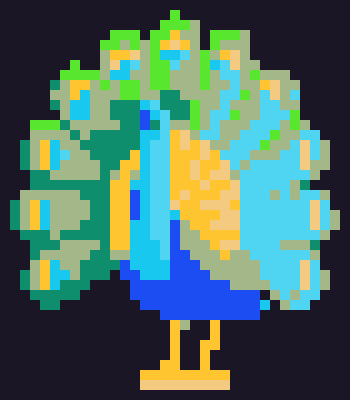
Deterministic conversion preserves the bird, fanned tail, eye spots, legs, and dark negative space.
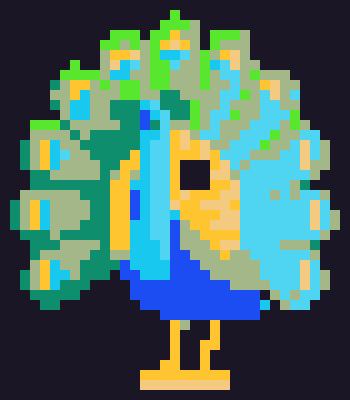
This sprite is the solution to the board but it is also a single, isolated sprite to which has been added the functionality of gameplay.
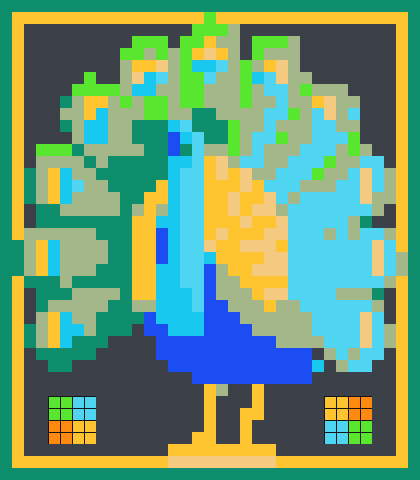
By using a regular border and flat fill the corpus of frames is filled with a density that reaches the point of being a reusable template rather than a level specific scene.
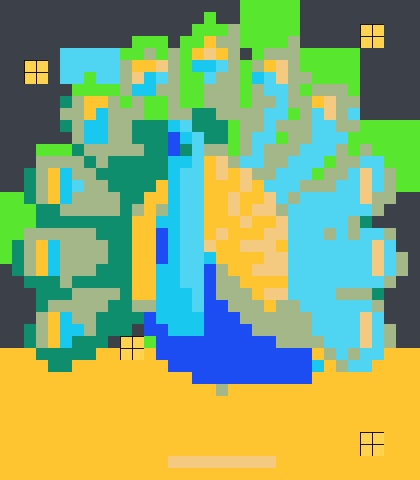
Four keys and locks to activate the viewer but they overwhelm the subject and don’t look like they were made for this scene.
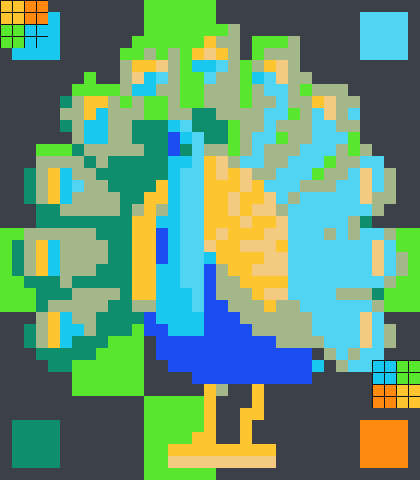
All the elements, including the mechanics, are positioned on the periphery of the bird. The bird is the dominant feature and the connected groups create pressure without obscuring the image.
The metrics reveal why aggregate scores were dangerous
The first playable peacock was the lowest scoring of all the playable versions even though it had the best static fit. The use of a dense frame to make the bird bigger meant that the level’s static fit was reduced. The scenic-key version scored as well as the accepted version on all three gate counts, although of course the human had to make the final decision between them.
Looking at the useful movement in the level, the average tray occupancy for this level was 2.03 which is very close to the recent-corpus median of 2.12 while the average available actions was a healthy 1.69. The level created a lot of sustained pressure without forcing a specific solution.
Peacock metrics across successive playable revisions
| Revision | Occupied | Static | Temporal | Richness | Mean tray | Mean choices | Verdict |
|---|---|---|---|---|---|---|---|
| One Pixel Pipe | 54.9% | 11/13 | 2/4 | 6/6 | 0.97 | 1.57 | revise |
| Solid field + frame | 100% | 9/13 | 2/4 | 5/6 | 1.48 | 1.74 | revise |
| Scenic keys | 100% | 10/13 | 2/4 | 6/6 | 1.14 | 1.60 | reject |
| Peripheral Egg Boxes | 100% | 10/13 | 2/4 | 6/6 | 2.03 | 1.69 | accept |
Mean tray occupancy and available actions through peacock revisions
The agent changed from generator to editor
In practice the improved agent did not solve a single level in one shot. Rather, it was able to keep the art frozen and yet consider many composition variants. It addressed a single issue (one thesis), modified a small area of the level, ran it, measured it, rendered it and then compared it with other ‘shipped’ levels nearby. All branches were kept – they could be useful as evidence for why a particular decision was taken or as a starting point for further development.
The production loop
Success improved gradually, not magically
We had zero jointly acceptable levels of play in the first full pack. A nine run repeatability test found 2 of the 54 boards reviewed to play and look well in gameplay and visual review. Later production review found 4 of the 5 boards reviewed to look well and play well. The one that did not look well and play well in production review actually exposed a real gate in human acceptance that we had not seen before in the previously reviewed cases.
Joint gameplay + visual acceptance by cohort
What the project actually learned
Semantic truth is its own gate
Color and structure can represent material, but they cannot prove the existence of a named subject. Source conversion had to be deterministic and get reviewed by a human.
Solvability is necessary, never sufficient
This is not sufficient to judge if a level is interesting to play. A replay certificate shows that a level can be won following the rules, but it does not say that it is fun to play it.
Progression has local context
Level 151 fits into the recent corpus of levels as well as serving as the first level in a new batch of levels. Global averages would render this level uninteresting.
Pressure must remain recoverable
The objective was set with designed pressure and relief which was all within the bounds of solvable without the use of a booster.
Composition beats feature count
One cannot assume that four keys automatically would result in a far richer experience than two Egg Boxes. The accepted mechanics supported the subject’s hierarchy and raised useful tray pressure.
Small loops produce better evidence
Local edits were traceable back to the regression case and thus proven to fail. Saved variants of images demonstrated which of the different aspects (density, framing, mechanic) of a certain thesis were successfully transferred to other images of the same subject.
The bigger insight was a better unit of work: a saved image plus a playable version to test your hypothesis plus a measureable outcome after a replay of the game plus your eyeball + more.
Provenance
All figures are derived from local development artifacts. “Acceptance” means joint human visual approval and deterministic winning replay within the stated cohort. Designed-pressure metrics are offline proxies, not player telemetry or conversion measurements.